TRANSFORMERLAYER STACK.
A SEQUENCE OFTRANSFORMER LAYERSPROCESS INFORMATIONTHROUGH ATTENTION,FEED-FORWARD NETWORKS,AND RESIDUALCONNECTIONS.
- = sequence length
- = model dimension
- = layer index
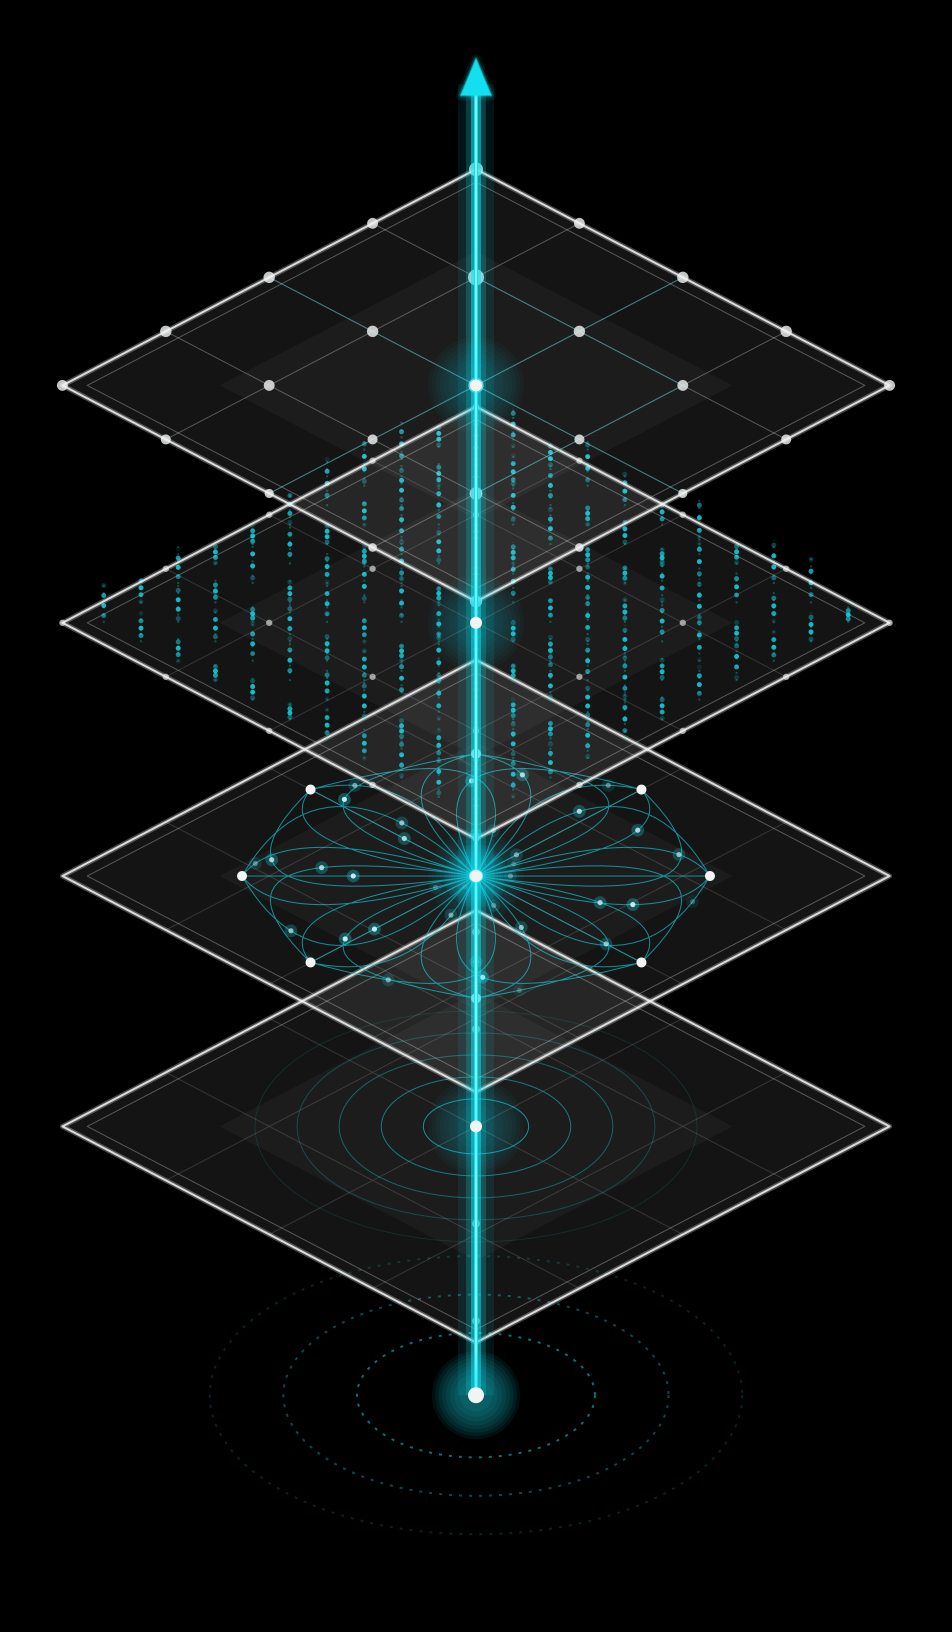
FORWARD
PASS
(inference)
Add & NormFeed-ForwardAdd & NormSelf-AttentionAdd & NormBACKWARD
PASS
(backpropagation)
Grad throughAdd & NormGrad throughFeed-ForwardGrad throughAdd & NormGrad throughSelf-AttentionGrad throughAdd & NormLAYER NORM
Normalize activations
for stable training.
FEED-FORWARD (MLP)
Non-linear transformation
applied token-wise.
SELF-ATTENTION
Global information flow
across sequence positions.
LAYER NORM
Pre-normalization
before attention.
LAYER NORM
Normalize activations for stable training.
FEED-FORWARD (MLP)
Non-linear transformation applied token-wise.
SELF-ATTENTION
Global information flow across sequence positions.
LAYER NORM
Pre-normalization before attention.
FORWARD PASS
(inference)
- Add & Norm
- Feed-Forward
- Add & Norm
- Self-Attention
- Add & Norm
BACKWARD PASS
(backpropagation)
- Grad throughAdd & Norm
- Grad throughFeed-Forward
- Grad throughAdd & Norm
- Grad throughSelf-Attention
- Grad throughAdd & Norm

TransformerLayers &Backpropagation
Motion Design Style-Frame Book
A VISUAL EXPLORATION OFTHE MATHEMATICS, MECHANISMS AND BEAUTYBEHIND MODERN ARTIFICIAL INTELLIGENCE.
FORWARD PASS
Residual streamLayer normFeed-forward (MLP)Self-attentionLayer normSequence inputtokens (embeddings)
BACKWARD PASS
Gradients toinput embeddings